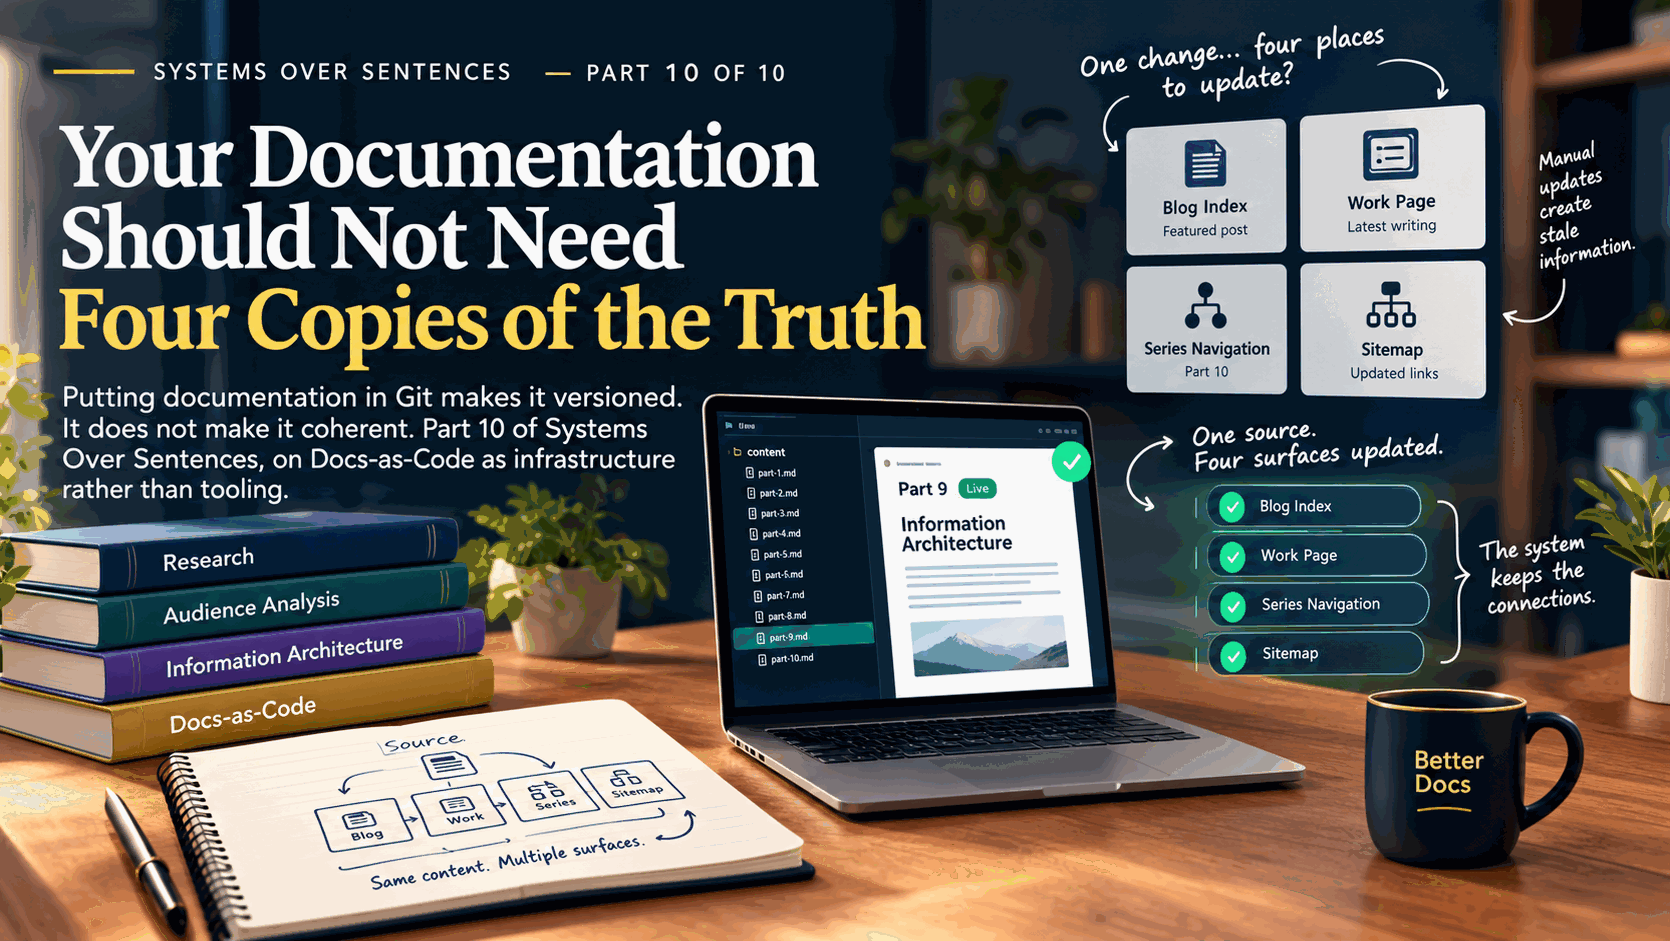
For days, possibly weeks, my own site was quietly telling readers the wrong thing about my latest writing.
That is a story about Docs-as-Code, and about the gap between having documentation in a repository and having a system that keeps it coherent.
I did not find it by checking. I opened the Work page to see whether that section still matched my brand standards, and there it was: three cards under a heading that said Latest Writing, and not one of them was the piece I had just published. Part 7 was live. The repository knew. The blog index knew. The Work page was still recommending older work.
I cannot tell you how long it had been wrong, because nothing told me. No build failed. No link broke. The page looked exactly as it was designed to look. It was simply out of date, and it would have stayed out of date for as long as I did not happen to look at it.
Fixing it took two minutes, and that was the part that bothered me. I had already published the article. Why was I still walking around my own site telling it about something it already contained?
The Problem Was Not Git
By any description I would have given at the time, I was already doing Docs-as-Code. The content lived in a repository. Everything was versioned. The site was generated from those files by a build. Branches, history, review, deployment on push, all of it was in place.
And I was still maintaining the same fact in four places by hand.
Those two things are often treated as the same thing, and they are not. Putting documentation in Git makes it versioned. It does not make it coherent. A repository can record every change you make and still leave you personally responsible for remembering every other place that change was supposed to reach. Git can tell you what changed. It cannot know what that change was supposed to keep true.
One Fact, Four Surfaces
Publishing a post on my site meant remembering the post itself, the featured block at the top of the blog index, the series strip beneath it, the grid of cards below that, the Latest Writing strip on the Work page, and the sitemap. Most of those I updated out of habit. The Work page I forgot, because it sits on a page I have no reason to open while publishing.
A checklist would have caught it. But a checklist is a person promising to remember a relationship the system knows nothing about. At that point the workflow depends on memory, and memory is the least reliable component in any system.
Memory is not infrastructure.
The better question was never what do I need to remember to update. It is what should change when this file changes. The first is a systems question. The second is a memory test, and I had been quietly failing it for weeks.
“Publish the post. Then update the index, the strip, the grid, the Work page and the sitemap.”
Result: a truth that goes stale without telling you.“Publish the post. Everything that depends on it derives from the post itself.”
Result: one place where being right is enough.One Source, Many Surfaces
The article already knew almost everything those other surfaces were displaying. Its title. Its date. Its part number. Its image. Its excerpt. Its place in the series. None of that needed to be typed into another file. It needed to be readable from the file that already held it.
So I changed the relationship rather than the content. Those facts were already sitting at the top of each post as structured metadata, which is the part that matters: they were not prose the build had to interpret, they were fields it could read. That turns a post from a document into something the site can query. Every surface that showed something about a post stopped keeping its own copy and started asking the posts themselves.
That sounds like an implementation detail, and it is not. It moves a responsibility. The writer creates the source. The system creates the representations.
To prove it worked, I created a temporary post, gave it a part number, and rebuilt the site. The featured block changed. The series strip changed. The grid changed. The strip on the Work page changed. Four surfaces, one file, no other edits. Then I deleted the test post, rebuilt, and everything went back.
My first reaction was not satisfaction. It was mild irritation. Every one of those manual updates I had been carefully making, and occasionally forgetting, had been unnecessary. That work was never part of writing. It was a consequence of how I had built the thing.
Automation Is Not the Point
It is easy to reduce Docs-as-Code to a list of tools. Git, Markdown, pull requests, continuous integration, a static site generator, linters. Those matter, and I use all of them. But the tools are not the idea.
The idea is that documentation should behave like an engineered system. A change should have one known source. Relationships should be explicit rather than remembered. Changes should be reviewable. The published result should be reproducible from the source. And repeated information should be derived, not synchronised by hand.
What that buys the writer is attention. If the system handles mechanical consistency, I am no longer asking whether I updated the other page. I am asking whether this is still the right information for this reader. The first question is maintenance. The second one is the work.
The Decisions Have to Survive
That shift matters more than it sounds, because attention is what the rest of this series was asking for. Parts 6 through 9 were about decisions. Research establishes what is true. Audience analysis decides what belongs. Architecture decides how the pieces relate. Each is a judgement a writer makes, and each is fragile in the same way: it exists in the writer’s head, and nothing outside that head enforces it.
Decide that every part of a series should stand on its own, and the decision holds only as long as you remember to write it into every page. Decide that a card should always carry a post’s title, date and excerpt, and the decision starts drifting the moment those values are copied into a second file. Decide that publishing should place a post in the right index, and you have described a build step rather than a rule, until the build actually performs it.
That is what this last part is for. Not a tool bolted onto the end of a series about thinking, but an answer to the question the thinking eventually forces. How do these decisions survive contact with a real project, over time, when the person who made them has forgotten the details?
Change something in your documentation that appears in more than one place: a product name, a version number, the title of a page. Then count how many places you have to update by hand. For each one, ask whether it genuinely needs its own editorial decision, or whether it is a copy the system could have derived from the source. Some will be genuine. The rest are relationships you are currently maintaining with memory, and every one of them is waiting to go stale without telling you.
The Work page failure was small. Nothing broke, nobody was blocked, no customer lost access to anything. That is exactly why it is worth ending on. It was not caused by carelessness, and being a more careful writer would not have prevented it. It was caused by an architecture that allowed one fact to live in four places, and offered no signal when three of them were right and one was wrong.
When documentation keeps going wrong in small ways, the instinct is to be more careful. Usually the better answer is to stop asking the writer to compensate for the system.
This series began with a phrase I use about my own work: narrative is infrastructure. Ten parts later, I can say what I actually mean by it. The words are the visible part. Underneath them sit decisions about what is true, what belongs and how it all relates, and those decisions are only as durable as the system holding them. Build the system, and the writing has somewhere to stand.
The writer decides what the documentation means. The system keeps that meaning from drifting.
Discussion