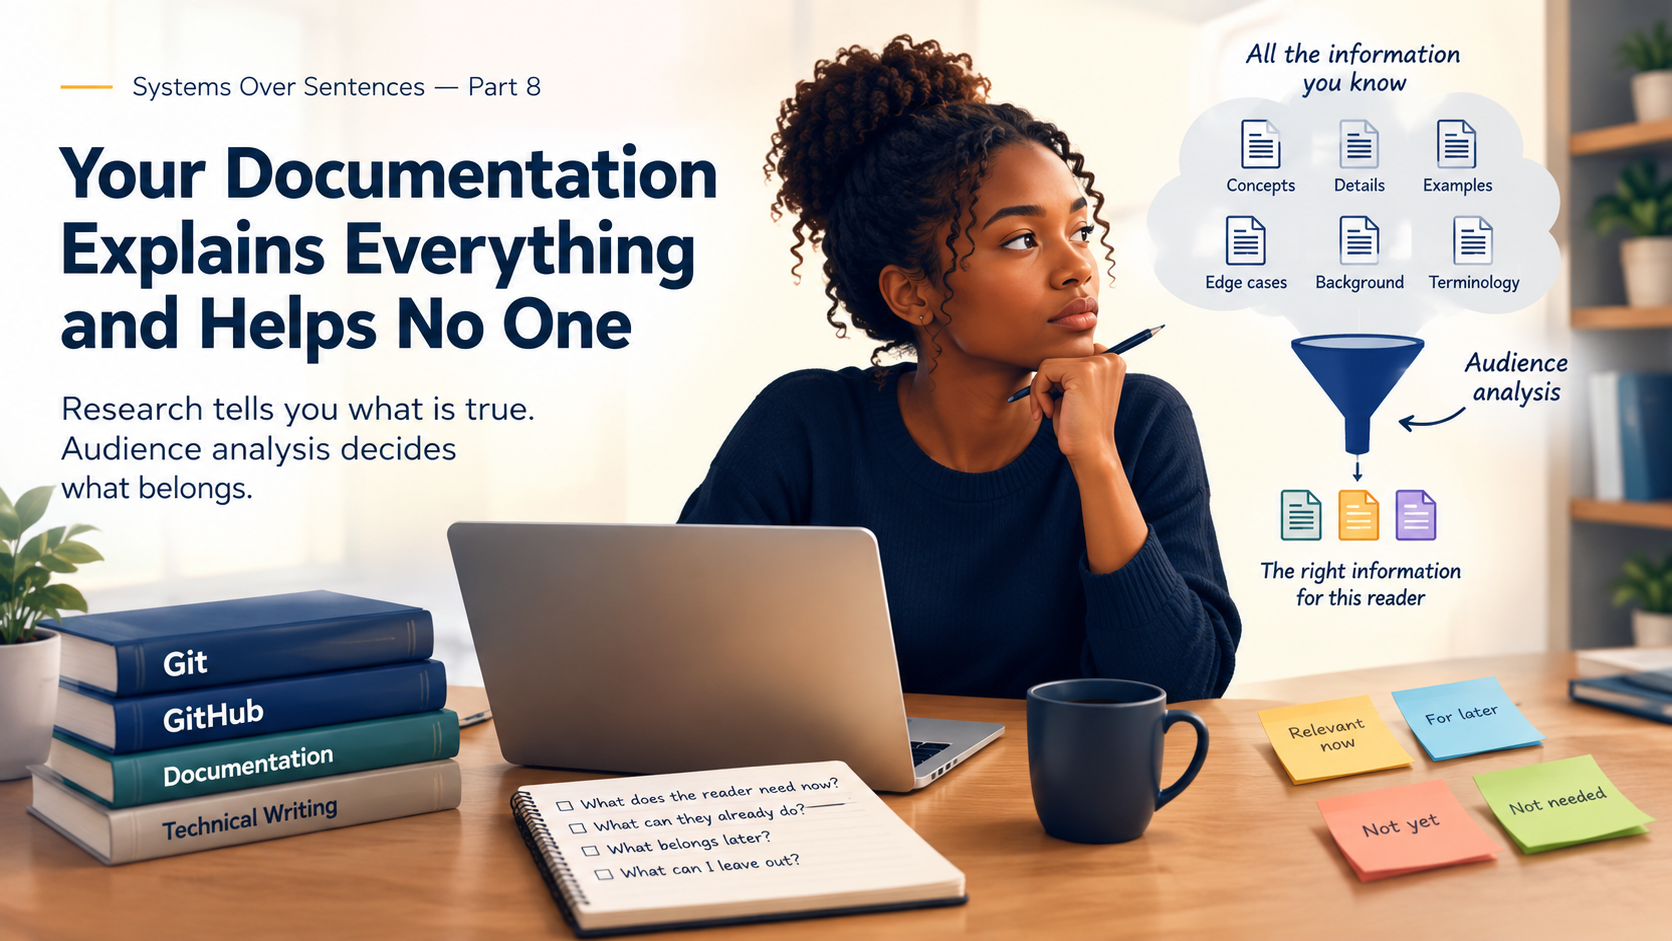
I left rebasing out of a six-part guide to Git, and it was the best decision in the whole series.
When I sat down to write Git & GitHub for Technical Writers, I was not short of material. I had spent real time with Git, with GitHub, and with the relationship between the two, and I had a body of knowledge I was confident would be useful to other writers. What I had not yet made was the decision that actually shapes a document.
Rebasing is not an obscure corner of Git. It is one of the first things a developer will tell you to learn, and any serious treatment of the tool covers it. Leaving it out of a guide aimed at technical writers felt, at first, like an omission I would have to justify.
Then I looked at what the reader was actually there to do. A technical writer adopting Docs-as-Code needs to commit their markdown, push it, open a pull request, and not lose their work. Git and GitHub are engineering tools. For a writer they are borrowed tools, picked up for a narrow and specific purpose. Rebasing serves a concern that belongs further inside that world: rewriting commit history to keep it linear, a thing engineering teams care about and a writer, at that stage, does not. Explaining it would not have made the reader more capable. It would have introduced a second mental model of how commits move, alongside merging, before the first one had settled.
The information was accurate. It was genuinely useful. It simply did not belong in that document, for that reader, at that point. That is the decision this post is about.
Part 7 was about research: how you find out what is true, and how widely true it is. This is the stage that comes next. Research produces more than any single document should contain, and audience analysis is what decides which of it survives.
Knowledge creates a temptation
The trap is easy to fall into, especially early on. You learn something difficult, you finally understand it, and you want to explain it. So the terminology goes in, and the background, and the edge cases, and the exceptions, and the thing that took you three hours to work out. Before long the document has become a record of the writer’s learning rather than an answer to the reader’s problem. Nothing in it is wrong. The writing may be perfectly good. But the reader is being asked to process information they have no reason to process yet.
There is a reliable tell for this, and it is visible in the shape of the document rather than in any sentence. A document written for the reader gets longer where the task is hardest. A document written for the writer gets longer where the learning was hardest. Those are rarely the same place. Find the section you expanded most, ask whether the difficulty you were answering was the reader’s or your own, and you will usually know the answer before you finish asking.
Information can be true, useful, and still not belong in the document you are writing.
The reader may not be ready for it. They may have already outgrown it. Or they may simply never need it for the task in front of them. The writer has to decide which, and the deciding is the work. The question is not what do I know that I can explain. It is what does this particular reader need to know right now. That distinction sounds small, and it is not.
The shift: warehouse versus kit
“I learned all of this, and all of it is true, so all of it should be in here somewhere.”
Result: an inventory the reader must search.“This reader is going somewhere specific. What do they need to take the next step, and nothing more.”
Result: only what this job requires.A warehouse is not a failure. An API reference is a warehouse and ought to be one: the reader arrives already knowing the name of the thing they want, and the only job is to hold it, accurately, under that name. Completeness is the whole value, and selecting on the reader’s behalf would destroy it.
What breaks a warehouse is a reader who does not yet know what they are looking for. Searching an inventory requires already knowing the term, and someone adopting an unfamiliar workflow has no term to search with. They need the set chosen for them by someone who knows which items matter and which ones will only slow them down.
So the question is never which kind of document is better. It is which one the reader in front of you needs. Most of the documents that fail are not warehouses by intention. They are kits that nobody pruned, grown item by item until the reader has to do the selecting themselves, which is the job they came to you to have done.
Selection happens before the sentence
Audience analysis is taught as a writing technique, something you apply to prose so it lands with the right reader. That is how I was taught it. In practice most of its value is spent earlier than that. It is a selection mechanism. Before you decide how to explain something, you decide whether it should be explained at all.
The questions that do this work are answered before the first paragraph exists. Who is this reader, and what are they trying to accomplish. What do they already know, and what can I reasonably assume. What is unfamiliar to them, and what have they already outgrown. What do they need to finish the task in front of them, what belongs later, and what is technically relevant but practically unnecessary. Answer those honestly and the document changes shape before a sentence is written.
There is a failure mode waiting for anyone who skips this. When you do not analyse the audience carefully, you invent one: an imaginary reader somewhere in the middle, not a beginner and not experienced, who supposedly needs a little of everything. The result is predictable. The beginner meets concepts they were not prepared for. The experienced reader wades through explanations they no longer need. The document grows longer without becoming more useful. Everyone receives information and nobody gets what they came for. That failure has a cost beyond the reading: every page written this way is another page the team maintains, updates on release, and eventually has to reconcile with a product that has moved on.
Selection is not only in or out. The same concept can enter a document at very different depths, and choosing the depth is this decision made at finer resolution. Branching is the example I keep returning to. A writer needs to know that a branch is a safe, separate copy of the work, how to make one, and how to get changes back into the main line. That is enough to work confidently for months. The full model underneath it, branches as movable pointers to commits, how the graph is actually assembled, is the same subject at a depth that answers questions the reader has not asked yet. Same concept. Two documents. The choice is not what is true about branching. It is how much of that truth this reader can use today.
The uncomfortable part
There is a humility required here that took me a while to accept. We become attached to information because we worked hard to learn it. Something cost three hours, so it feels like it has earned its place. But the effort it took the writer to acquire a piece of knowledge says nothing about its value to the reader. A concept can be genuinely difficult for me to learn and completely unnecessary for you to know.
That makes the cut hard in a way that has nothing to do with judgement and everything to do with attachment. The reader never experiences your research. They do not know how many sources you consulted or how many concepts you turned over. They experience the document, and they judge it by whether it helped them do the thing they came to do. The filtering has to happen before it reaches them, or they end up doing it themselves, which is the job you were hired to do.
So a technically impressive document can still be a badly designed one. Accurate explanations, thorough research, careful examples, and it can still fail, because it asked the wrong reader to carry the wrong information at the wrong time. The problem was never the knowledge. It was the selection.
Compressed into something you can apply, the decision comes down to three questions asked of every piece of information before it earns a place. Rebasing failed all three at once, which is why the cut was easy in the end. Most cuts are not that clean, and the questions are what make the difficult ones decidable.
Open something you have written and find one section you included because you knew it, not because the reader needed it. Then put it through the three questions:
- Does it serve the task the reader came to complete?
- Does including it force a second mental model before the first one has settled?
- Is it needed today, or does it belong in the document this reader reaches next?
If it fails all three, cut it and read the document again without it. Notice whether anything was actually lost. That is the test, and it is uncomfortable the first few times.
Research tells you what is true. Audience analysis tells you what belongs. What neither tells you is the order it should arrive in, and a document with exactly the right information in the wrong sequence still fails the person reading it. That is information architecture, and it is where Part 9 begins.
Six parts, and rebasing is in none of them. Everything the guide does not say was decided as carefully as everything it does.
Discussion